Text classification
Sort emails, tickets, and documents into the categories your teams use.
Turn emails, documents, and conversations into structured information. Shaaneiol Tech builds natural language solutions that read, classify, and extract meaning from text at scale.
Clear text understanding. Reliable results. Easy to integrate.
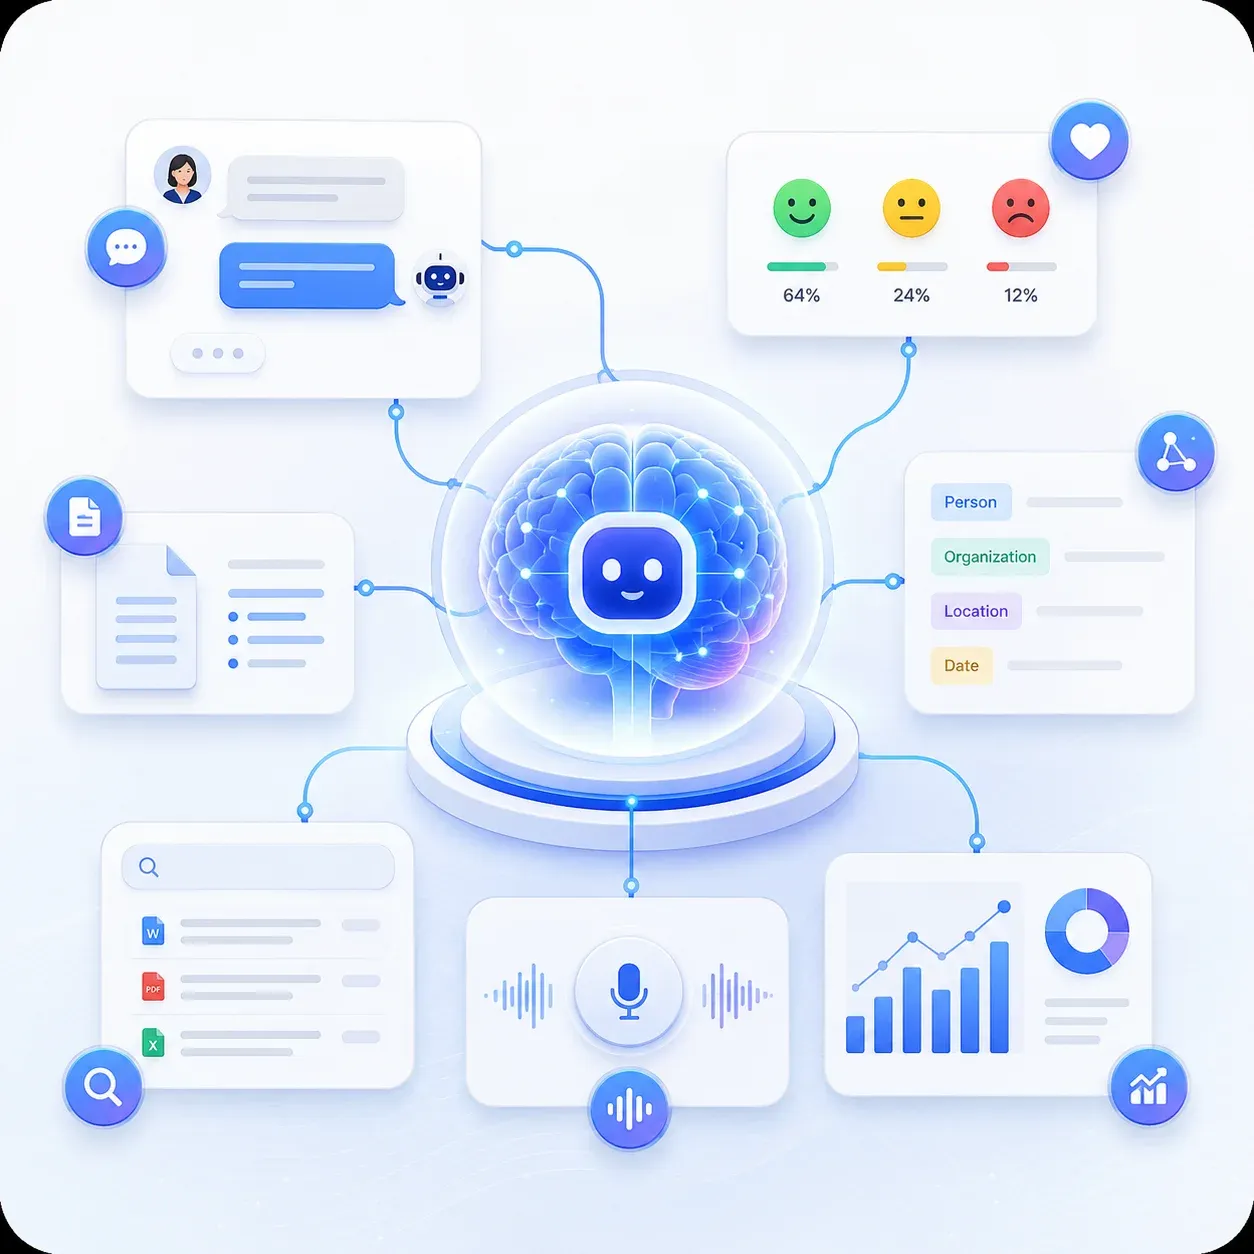
From raw text to structured data, a connected approach to teaching software to read.
Sort emails, tickets, and documents into the categories your teams use.
Pull names, dates, amounts, and key fields out of unstructured text.
Shorten long documents and threads into clear, accurate summaries.
Understand how customers feel and what they want from messages and reviews.
Work across languages with detection, translation, and consistent terminology.
Power chat and voice features that understand questions in natural language.
A clear delivery path, with priorities you can understand and progress you can follow.
Review your text sources and what you need from them.
Prepare examples so the model learns your categories.
Train, test, and tune the language model.
Connect results to your tools, forms, and workflows.
Check accuracy over time and retrain as language changes.
Match each language task with the method that fits your data and accuracy needs.
Trained models. Measured accuracy. Easy integration.
What text you have, its quality, and what to label first.
Examples prepared for training and testing.
A tuned model for your categories and fields.
A simple interface your systems can call.
Precision, recall, and error examples in plain language.
How to retrain, monitor, and extend the solution.
Combine the right models with your own examples, with results you can measure and explain.
Start from your own emails, documents, and conversations. Use the simplest method that meets your accuracy needs, and show how it reaches each result.
Clear scores on your own data, not generic benchmarks.
Support for many languages and local terminology.
Simple interfaces for your apps, forms, and workflows.
Sensitive text handled with access control and care.
Can’t find what you need? Let’s have a quick, no-pressure conversation.
Cost depends on the task, the amount of labeling, and integration needs. We start small, measure accuracy, and give a clear estimate before scaling.
Often fewer examples than people expect. Modern language models can start from a few hundred labeled examples and improve as you add more.
Yes. We work with many languages and can combine detection, translation, and language-specific models where needed.
It depends on your text and task. We test on your own data, report precision and recall openly, and tune until results meet an agreed target.
Turn text into structured, useful data with engineers who build language AI that fits your systems.